Next Batch : Invalid Date
You've cleaned your dataset, selected an algorithm, and trained your first machine learning model. The accuracy isn't terrible, but something feels off. You try adjusting the model's parameters, hoping for better results.
What if the problem isn't the algorithm?
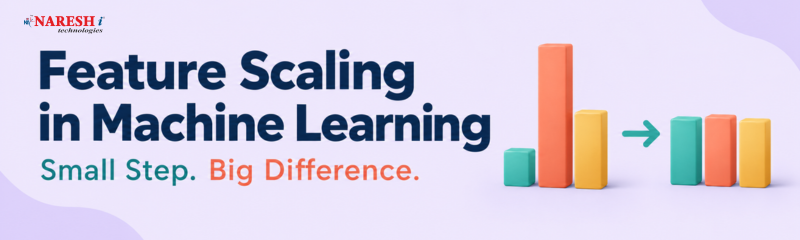
Sometimes, the trouble starts with the numbers going into it. Imagine a dataset containing customer ages between 18 and 65 and annual incomes ranging from ₹2 lakh to ₹30 lakh. Both features matter, but their numerical scales are quite different.
For certain algorithms, that difference can affect the calculations. Feature Scaling in Machine Learning addresses this issue before training begins.
Suppose you're developing a customer segmentation model using age and annual income.
K-Means clustering groups similar customers by calculating distances between observations. When income is represented by much larger numbers than age, income differences can dominate those distance calculations.
Your clusters may reflect income patterns much more strongly than age differences, even when both features deserve consideration.
This illustrates the Importance of Feature Scaling in Machine Learning. It isn't about making every column look tidy. It's about preventing measurement units from unintentionally influencing certain mathematical operations.
Scaling changes the numerical representation of a feature. It doesn't change which customer is older or which property costs more when using common positive linear scaling methods.
Consider three house sizes: 800, 1,200, and 1,600 square feet.
After Min-Max scaling, those values become 0, 0.5, and 1. The numbers look different, but their order and relative spacing remain intact.
Think of converting distances from metres to kilometres. The measurements change, but the physical distances don't.
Scaling works on a similar principle, although different techniques use different calculations.
Min-Max scaling maps the training feature's minimum and maximum values to a selected range, usually 0 to 1.
It is useful when an algorithm or application benefits from bounded numerical inputs.
There is one catch: unusually large or small observations can compress most ordinary values into a narrow range.
Standardization subtracts the feature's mean and divides by its standard deviation.
The transformed training feature has a mean near zero and a standard deviation of one.
StandardScaler in Machine Learning is commonly used with algorithms such as Support Vector Machines and regularized logistic regression.
Unlike Min-Max scaling, standardization doesn't restrict values to a fixed interval.
What if a salary dataset contains a few extremely high earners?
Those observations can heavily influence the mean and maximum. RobustScaler instead uses the median and interquartile range, making its scaling parameters less sensitive to extreme values.
However, the outliers remain in the dataset.
Choosing between Normalization and Standardization in Machine Learning depends on the model and the data.
|
Technique |
How it works |
What to remember |
|
Min-Max Scaling |
Uses minimum and maximum |
Sensitive to extreme values |
|
Standardization |
Uses mean and standard deviation |
Doesn't create fixed bounds |
|
Robust Scaling |
Uses median and interquartile range |
Less affected by outliers |
There's no universal winner. Try appropriate methods and compare results using validation data.
Let's use a small dataset containing three observations.
Feature Scaling Using Scikit-learn can be demonstrated with this code:
import numpy as np
from sklearn.preprocessing import StandardScaler, MinMaxScaler
values = np.array([[10], [20], [30]])
standard = StandardScaler().fit_transform(values)
minmax = MinMaxScaler().fit_transform(values)
print(standard.round(2).ravel())
print(minmax.ravel())
Output:
[-1.22 0. 1.22]
[0. 0.5 1. ]
Notice that the same data produces different values depending on the technique.
The order of observations remains unchanged. What changes is the scale used in subsequent calculations.
This simple Feature Scaling in Python exercise is a useful starting point before applying preprocessing to larger datasets.
KNN, K-Means, SVM, and many regularized linear models are sensitive to feature scales.
Decision Trees and Random Forests are different. They work primarily through feature-based splits, so ordinary feature scaling is generally unnecessary.
Principal Component Analysis also deserves attention because features with larger variance can dominate the extracted components.
Before applying any of the available Feature Scaling Techniques, ask how your chosen algorithm uses numerical values.
One common beginner mistake is scaling the entire dataset before creating training and test sets.
That exposes the preprocessing step to information from the test data.
Your evaluation may then look more reliable than it actually is.
Split the dataset first. Fit the scaler using training observations only, then apply that same fitted transformation to the test set.
Scikit-learn's Pipeline functionality is particularly useful here because preprocessing can be included inside the model-training workflow.
Feature scaling is a small part of Data Preprocessing in Machine Learning, but understanding it demonstrates something employers value: the ability to question model results.
For a portfolio project, train a KNN classifier with and without scaling. Record the validation scores and explain any differences.
Even if performance barely changes, that observation is worth discussing.
A developer who can explain why a preprocessing decision matters is better prepared for practical machine learning work than someone who simply copies a training script.
No. Tree-based algorithms generally work without feature scaling, while distance-based algorithms are often sensitive to numerical ranges.
Yes, it can improve some models, although better accuracy is not guaranteed. Check the results through proper validation.
MinMaxScaler uses feature minimums and maximums, while StandardScaler uses the mean and standard deviation.
No. Scaling transforms values but doesn't delete unusual observations. RobustScaler can reduce their influence on scaling parameters.
Apply it after splitting the dataset. Fit the scaler on training data and reuse it for validation and testing.
A machine learning model can struggle for reasons that have little to do with its algorithm. Sometimes, the measurement scales of its inputs are part of the problem.
Before spending hours tuning parameters, inspect your features and consider whether scaling is appropriate.
Discussion Question: When building an ML model, do you compare results with and without scaling, or follow the same preprocessing routine every time?
Follow NareshIT for more practical insights on technology, skills, and career development.
 +91 8179191999

 +91
8179191999