A developer once spent half a day debugging why his chatbot kept cutting off mid-sentence, convinced there was a bug in his code. There wasn't. He'd hit the model's token limit by stuffing an entire 40-page document into a single prompt, and the response he got back was simply as much as fit before the limit ran out. Nothing was broken. He just didn't yet understand the unit everything gets measured in.
That's a common starting point for developers new to this space: the Python code itself is usually the easy part, sending a request, receiving a response, is a handful of lines. What actually takes learning is understanding the concepts underneath the API call, tokens, context windows, structured output, embeddings, well enough to know why something behaves the way it does instead of guessing.
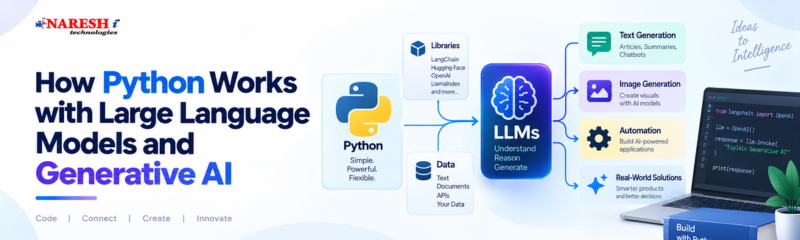
This piece walks through the mechanics of how Python actually connects to and works with large language models, the parts that matter once you move past a basic "hello world" API call.
Underneath everything, Python talks to a language model over an HTTP API, sending a request with your message and getting a JSON response back. The provider's Python SDK just wraps that HTTP call in a friendlier interface:
python
import anthropic

client = anthropic.Anthropic()

response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=300,
    messages=[{"role": "user", "content": "Explain what a context window is, briefly."}]
)

print(response.content[0].text)
Nothing here is exotic. It's a network request like any other API call you've made in Python, requests library, JSON payload, structured response. What makes working with language models distinct isn't the transport mechanism, it's the handful of concepts around what you send and what constraints govern what comes back.

A token is roughly a chunk of a word, not a whole word and not a single character, somewhere in between. "Understanding" might break into two or three tokens depending on the model's tokenizer. This matters because every limit you'll run into, how much text you can send, how long a response can be, how billing works, is measured in tokens, not characters or words.
The developer in the introduction ran into the context window limit: the maximum number of tokens a model can consider at once, input and output combined. Send a 40-page document as input, and there's simply less room left for the response before that ceiling is reached. You can check roughly how many tokens a piece of text will consume before sending it:
python
def estimate_tokens(text: str) -> int:
    # Rough estimate: about 4 characters per token for English text
    return len(text) // 4

document_tokens = estimate_tokens(long_document)
if document_tokens > 100_000:
    print("This document may exceed the context window on its own")
This is a rough approximation, real tokenization is more precise and provider-specific, but it's often enough to catch an obvious problem before it happens rather than after a confusing truncated response shows up in production.
A lot of real applications don't want a paragraph back, they want a specific piece of data: a category, a score, a list of fields, something the rest of the code can use directly without parsing free text. Asking the model to respond only in JSON, and validating that response, turns unpredictable prose into something your application can actually rely on.
python
import json

prompt = """Classify this customer message. Respond ONLY with JSON in this
exact format, nothing else:
{"category": "billing" | "technical" | "general", "urgent": true | false}

Message: "My payment failed twice and I need this resolved today."
"""

response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=100,
    messages=[{"role": "user", "content": prompt}]
)

result = json.loads(response.content[0].text)
print(result["category"], result["urgent"])
The instruction to respond "ONLY with JSON, nothing else" is doing real work here. Without it, models tend to add a friendly sentence before or after the JSON, which breaks json.loads() the moment it runs. This is a small detail that trips up a lot of first attempts at structured output.
Waiting several seconds for a complete response before showing anything feels sluggish, especially for longer answers. Streaming lets you display text as it's generated, word by word, the way most chat interfaces behave:
python
with client.messages.stream(
    model="claude-sonnet-4-6",
    max_tokens=500,
    messages=[{"role": "user", "content": "Write a short product description."}]
) as stream:
    for text in stream.text_stream:
        print(text, end="", flush=True)
This doesn't change what the model generates, only how your application receives and displays it. For a user-facing chat feature, this single change often has more impact on perceived speed than any amount of backend optimization elsewhere.
An embedding converts text into a list of numbers, a vector, positioned so that similar meanings end up close together in that numerical space. This is what makes semantic search possible: comparing a search query's vector against a set of document vectors to find the closest matches, even when the wording doesn't overlap exactly.
python
from sentence_transformers import SentenceTransformer
import numpy as np

model = SentenceTransformer("all-MiniLM-L6-v2")

documents = ["How to reset your password", "Billing cycle explained", "Cancel your subscription"]
doc_embeddings = model.encode(documents)

query_embedding = model.encode(["I forgot my login credentials"])
similarities = np.dot(doc_embeddings, query_embedding.T).flatten()

best_match = documents[np.argmax(similarities)]
print(best_match)  # "How to reset your password"
Notice the query never contains the word "password," yet it correctly matches the password-reset article, because the embedding captures meaning rather than exact word overlap. This is the mechanism behind most retrieval-based generative AI applications, matching by meaning rather than keyword.
A common, genuinely useful application combines several of these pieces: turning a raw meeting transcript into a structured list of action items, assigned owners, and due dates, something a team lead can scan in ten seconds instead of rereading a transcript.
python
prompt = f"""Extract action items from this meeting transcript. Respond
ONLY with a JSON array, each item having "task", "owner", and "due_date"
(use null if not mentioned).

Transcript:
{transcript_text}
"""

response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=800,
    messages=[{"role": "user", "content": prompt}]
)

action_items = json.loads(response.content[0].text)
for item in action_items:
    print(f"- {item['task']} ({item['owner'] or 'unassigned'})")
This combines structured output with a clear, bounded task, extract, don't summarize or editorialize, which keeps the model's response predictable enough to build a real feature around rather than something that needs manual review every time.
Beyond generating text, a model can be given a list of functions it's allowed to request, along with descriptions of what each does, and decide which one to call based on the conversation. Your Python code executes the actual function; the model just decides when and with what arguments.
python
tools = [{
    "name": "check_order_status",
    "description": "Look up the current status of a customer order by ID",
    "input_schema": {
        "type": "object",
        "properties": {"order_id": {"type": "string"}},
        "required": ["order_id"]
    }
}]

response = client.messages.create(
    model="claude-sonnet-4-6",
    max_tokens=300,
    tools=tools,
    messages=[{"role": "user", "content": "Where's my order #4521?"}]
)

if response.stop_reason == "tool_use":
    tool_call = response.content[-1]
    order_id = tool_call.input["order_id"]
    status = check_order_status(order_id)  # your actual function
This is the mechanism behind agentic applications: the model reasons about what information it needs, your code supplies it by running real functions, and the loop continues until the model has enough to respond.
A question that comes up early: should you just write a better prompt, or actually fine-tune a model on your own data?
|
S.No |
Aspect |
Prompting |
Fine-Tuning |
|
1 |
Setup effort |
Low, just write and iterate on the prompt |
High, requires a labeled training dataset |
|
2 |
Update speed |
Immediate, change the prompt and redeploy |
Slower, requires retraining |
|
3 |
Best for |
Most application logic, including RAG and tool use |
Consistent tone or format across huge volumes of similar tasks |
|
4 |
Cost pattern |
Pay per request, scales with usage |
Upfront training cost, then similar per-request cost |
|
5 |
Flexibility |
Easy to adjust as requirements change |
Harder to adjust without retraining |
Most Python applications never need fine-tuning at all. A well-structured prompt combined with retrieved context covers the majority of real use cases, and fine-tuning is worth the added complexity mainly when you need very consistent behavior at a scale where prompt-based approaches start to show cracks.
For a typical RAG-based application, it helps to see where token usage actually concentrates, since it's rarely the user's question itself:

A bar chart works better here than a pie chart, since these numbers can each grow independently as you tune retrieval settings or prompt length, rather than always summing to one fixed total worth showing as proportions. The pattern above reflects something worth knowing early: retrieved context usually dominates token usage, far more than the user's actual question, which is exactly why limiting how much context gets retrieved (the k value in a similarity search) has a bigger cost impact than most people expect going in.

The concepts here build on each other: understand a basic prompt-response call first, then tokens and context limits, then structured output, then retrieval, then tool use. Skipping straight to building an agent without understanding what a token limit actually constrains tends to produce confusing, hard-to-debug behavior later. A generative AI and agentic AI training program built around actual Python exercises, working with real APIs and a real vector store, rather than slide-based explanations, is where these concepts stop being abstract and start being intuitive.
This usually means you've hit the max_tokens limit you set, or the combined input and output exceeded the model's context window. Increasing max_tokens or trimming the input, particularly retrieved context in a RAG setup, usually resolves it.
No. Most Python work with embeddings involves calling a library to generate them and a vector database to compare them, without needing to understand the underlying vector math. Knowing what they represent, numerical closeness for meaning, is enough to use them effectively.
Use tool calling when the model needs real, current information your training data can't contain, an order status, a live inventory count, a calculation your code needs to perform accurately. If the model can answer from general knowledge or provided context alone, tool calling adds unnecessary complexity.
For most application-level work, no, prompting and retrieval cover the majority of practical needs. Fine-tuning becomes relevant at a scale or consistency requirement most projects don't reach, so it's reasonable to learn prompting and RAG thoroughly first.
A small tool that takes a document, breaks it into chunks, embeds them, and answers questions using retrieved context and structured output touches tokens, embeddings, retrieval, and prompt design all in one manageable project.
Python's role in working with large language models isn't really about the API call, that part is a handful of lines almost anyone can write. It's understanding the concepts governing what happens around that call: tokens setting real limits, structured output making responses usable, embeddings enabling retrieval, and tool use letting a model act on real information instead of just describing it.
If you're building toward a role involving generative AI and agentic AI with Python, understanding these mechanics thoroughly, before reaching for any particular framework, tends to save far more debugging time than it costs to learn upfront.

Which of these, tokens, structured output, embeddings, or tool use, do you currently understand the least, and would be worth digging into first?
Follow NareshIT for more practical insights on technology, skills, and career development.
 +91 8179191999

 +91
8179191999